Anthropic warns that the safeguards of the open model GLM-5.3 can be bypassed with simple techniques
On September 29, Anthropic published an analysis of GLM-5.3, the latest model from Zhipu AI (known outside China as Z.ai). According to its tests, this model can build complete exploits on its own, that is, programs that take advantage of a security flaw to attack a system, and its safeguards can be bypassed with simple techniques.
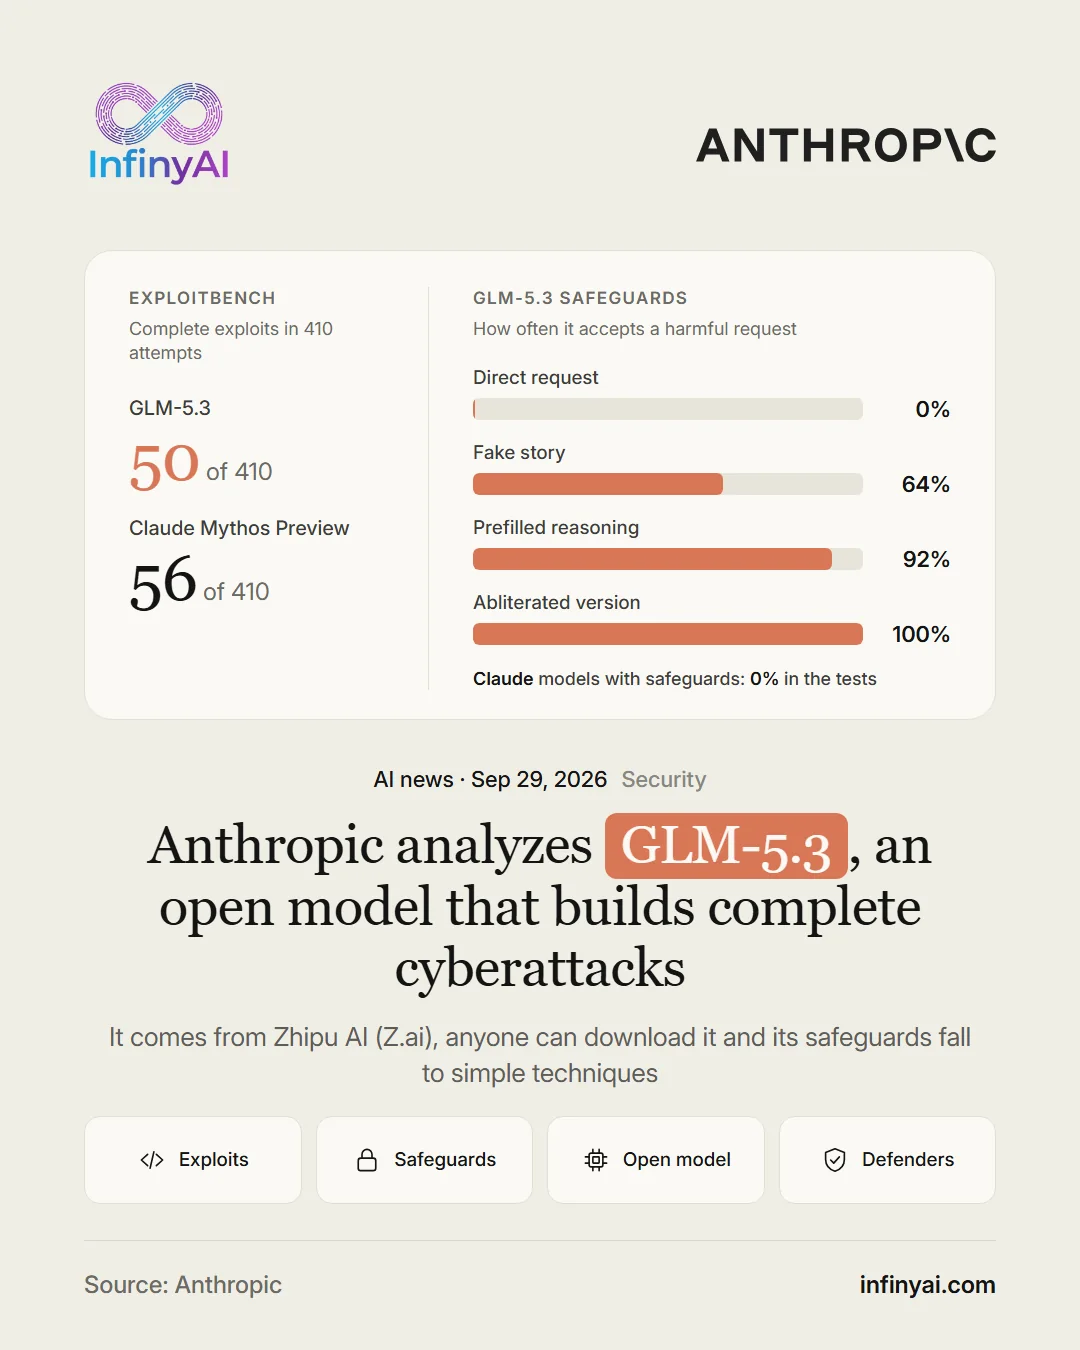
The tests were run in isolated environments. On ExploitBench, which measures whether a model can exploit known flaws in V8, the engine used by Google Chrome, GLM-5.3 achieved a complete exploit in 50 of 410 attempts. Claude Mythos Preview, the Anthropic model that has only been opened to trusted defenders, managed it in 56.
With a researcher in charge, GLM-5.3 found several unknown flaws in a popular browser in a single day and chained them into a web page that reads files from the visitor's computer. Anthropic says it has already notified the vendor. In another test, GLM-5.3-Flash, its smaller version, chained two already known flaws, one of them in Chrome, into a working attack. It took 20 minutes of human attention and 8 hours of model work, which at Zhipu's prices would have cost $20.40.
The difference Anthropic points to lies in the safeguards. GLM-5.3 is an open model that anyone can download and modify. Faced with a clearly harmful request, it usually refuses, but in the tests it complied 64% of the time with a fake story, 92% when its reasoning was prefilled in advance and 100% with a version modified to strip out its refusals. Several developers published versions like that within days of its launch. According to Anthropic, none of those techniques worked against the protected Claude models in its tests.
On September 17, CAISI (the Center for AI Standards and Innovation at NIST, the US standards institute) had already rated it the most capable open model in cybersecurity released to date.
Anthropic is asking governments to evaluate AI models with this capability and for defenders to have models at least as good as the ones attackers use.
We see a practical lesson for businesses. If, in one test, 20 minutes of attention and about $20 were enough to turn already known flaws into an attack, we believe that updating browsers, devices and software as soon as the patch is out is no longer something that can be put off.